Making Mapify faster—and its AI pipelines observable
Yingchen Liu
A performance and reliability programme spanning web vitals, streaming memory leaks, embedding memory and Prometheus monitoring.
- Web performance
- Node.js
- Observability
01
One Mapify request crosses the browser, AI streams and data pipelines
Mapify is an AI app that turns documents, videos, recordings and web pages into visual mind maps.
A result is assembled progressively. The browser first renders the product shell, then receives generated text and structured map content, and may later add images, speech transcripts or embedding-backed context. A slow experience can therefore come from the initial page, the streaming process, image delivery, model orchestration or memory pressure in a backend worker.
The measurements in this article describe different layers. First Contentful Paint is when the browser first shows useful content; Largest Contentful Paint tracks when the largest visible element finishes; process and embedding memory describe server-side resource use; Prometheus signals make those behaviours inspectable after deployment. Combining them into one generic ‘speed’ number would hide the actual failure mode.
02
The problem
Mapify combines a media-heavy web experience with long-running AI streams and vector embeddings. Performance problems appeared at different layers: slow critical rendering, images competing for bandwidth, streaming responses retaining strings, and embeddings consuming far more memory than expected.
Fixing one screenshot was not enough. Without runtime metrics, the same class of regression could return under a different workload.
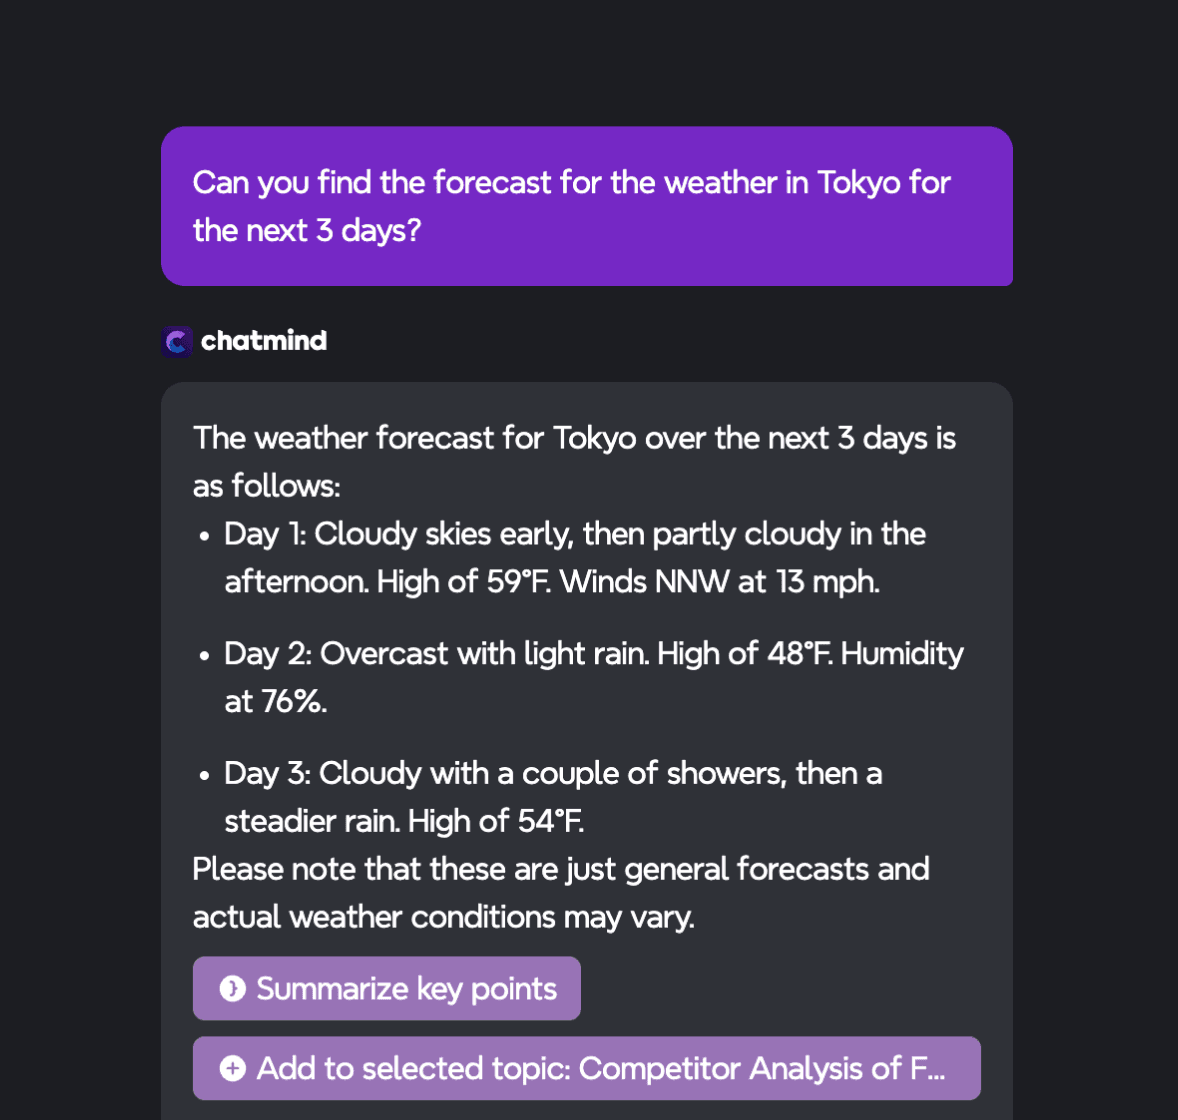
The page that has to appear in pieces
This is one surface those separate measurements cover. The answer arrives as text first, with actions and later images. The first useful frame and the memory held by the stream are different problems.
03
Measured before and after
Before → after
Lower is better. The web-vital timings and embedding-memory figures come from the performance work itself, not a synthetic portfolio estimate.
First Contentful Paint
11.6s → 1.1sLargest Contentful Paint
22.1s → 7.6sEmbedding memory
78MB → 22MBHow I implemented it
On the web I prioritised the critical route, corrected image loading and preload behaviour, and removed work that blocked the first useful frame. In the streaming path I eliminated repeated string concatenation that retained large intermediate values. In the embedding path I changed how vectors were held so memory fell from 78 MB to 22 MB for the measured workload.
I then added Prometheus monitoring with default process-memory metrics and product-specific signals. Speech-to-text gained retry and provider fallback so failures could be separated from slow or memory-constrained processing rather than appearing as one generic timeout.
04
The decision
I split the work into user-perceived latency, process memory and operational visibility. Each layer needed its own measurement and smallest effective fix. I avoided one large ‘performance rewrite’ because that would make it difficult to prove which change moved which number.
The decisions that shaped the system
- 01
Measure by failure layer
Web vitals, streaming retention and embedding memory each received their own baseline instead of one ambiguous speed score.
- 02
Remove retained work
The streaming fix targeted repeated string concatenation and large intermediates rather than hiding pressure behind a larger memory limit.
- 03
Keep the measurement in production
Prometheus process and pipeline signals turned the incident investigation into an ongoing performance capability.
05
What improved
First Contentful Paint dropped from 11.6 seconds to 1.1 seconds and Largest Contentful Paint from 22.1 seconds to 7.6 seconds in the measured flow. Embedding memory fell by roughly 72%. More importantly, later regressions had telemetry: the team could inspect process memory and pipeline behaviour instead of waiting for a user report.
06
What I learned
Performance work is strongest when the measurement survives the fix. A fast page without observability is a moment; a measured budget and visible runtime make it an engineering capability.
Takeaways
- Separate rendering, memory and reliability measurements.
- Prefer small changes whose effect can be attributed.
- Keep the telemetry after the incident is over.